
Introduction
Within the quickly evolving panorama of Synthetic Intelligence, Retrieval-Augmented Era (RAG) has emerged as a pivotal method for enhancing the factual accuracy and relevance of Giant Language Fashions (LLMs). By enabling LLMs to retrieve data from exterior data bases earlier than producing responses, RAG mitigates frequent points reminiscent of hallucination and outdated data.
Nevertheless, conventional RAG approaches typically depend on vector-based similarity searches, which, whereas efficient for broad retrieval, can generally fall quick in capturing the intricate relationships and contextual nuances current in advanced knowledge. This limitation can result in the retrieval of fragmented data, hindering the LLM’s potential to synthesize actually complete and contextually acceptable solutions.
Enter Graph RAG, a groundbreaking development that addresses these challenges by integrating the facility of data graphs instantly into the retrieval course of. Not like typical RAG methods that deal with data as remoted chunks, Graph RAG dynamically constructs and leverages data graphs to know the interconnectedness of entities and ideas.
This enables for a extra clever and exact retrieval mechanism, the place the system can navigate relationships throughout the knowledge to fetch not simply related data, but in addition the encircling context that enriches the LLM’s understanding. By doing so, Graph RAG ensures that the retrieved data just isn’t solely correct but in addition deeply contextual, resulting in considerably improved response high quality and a extra strong AI system.
This text will delve into the core rules of Graph RAG, discover its key options, show its sensible functions with code examples, and focus on the way it represents a major leap ahead in constructing extra clever and dependable AI functions.
Key Options of Graph RAG
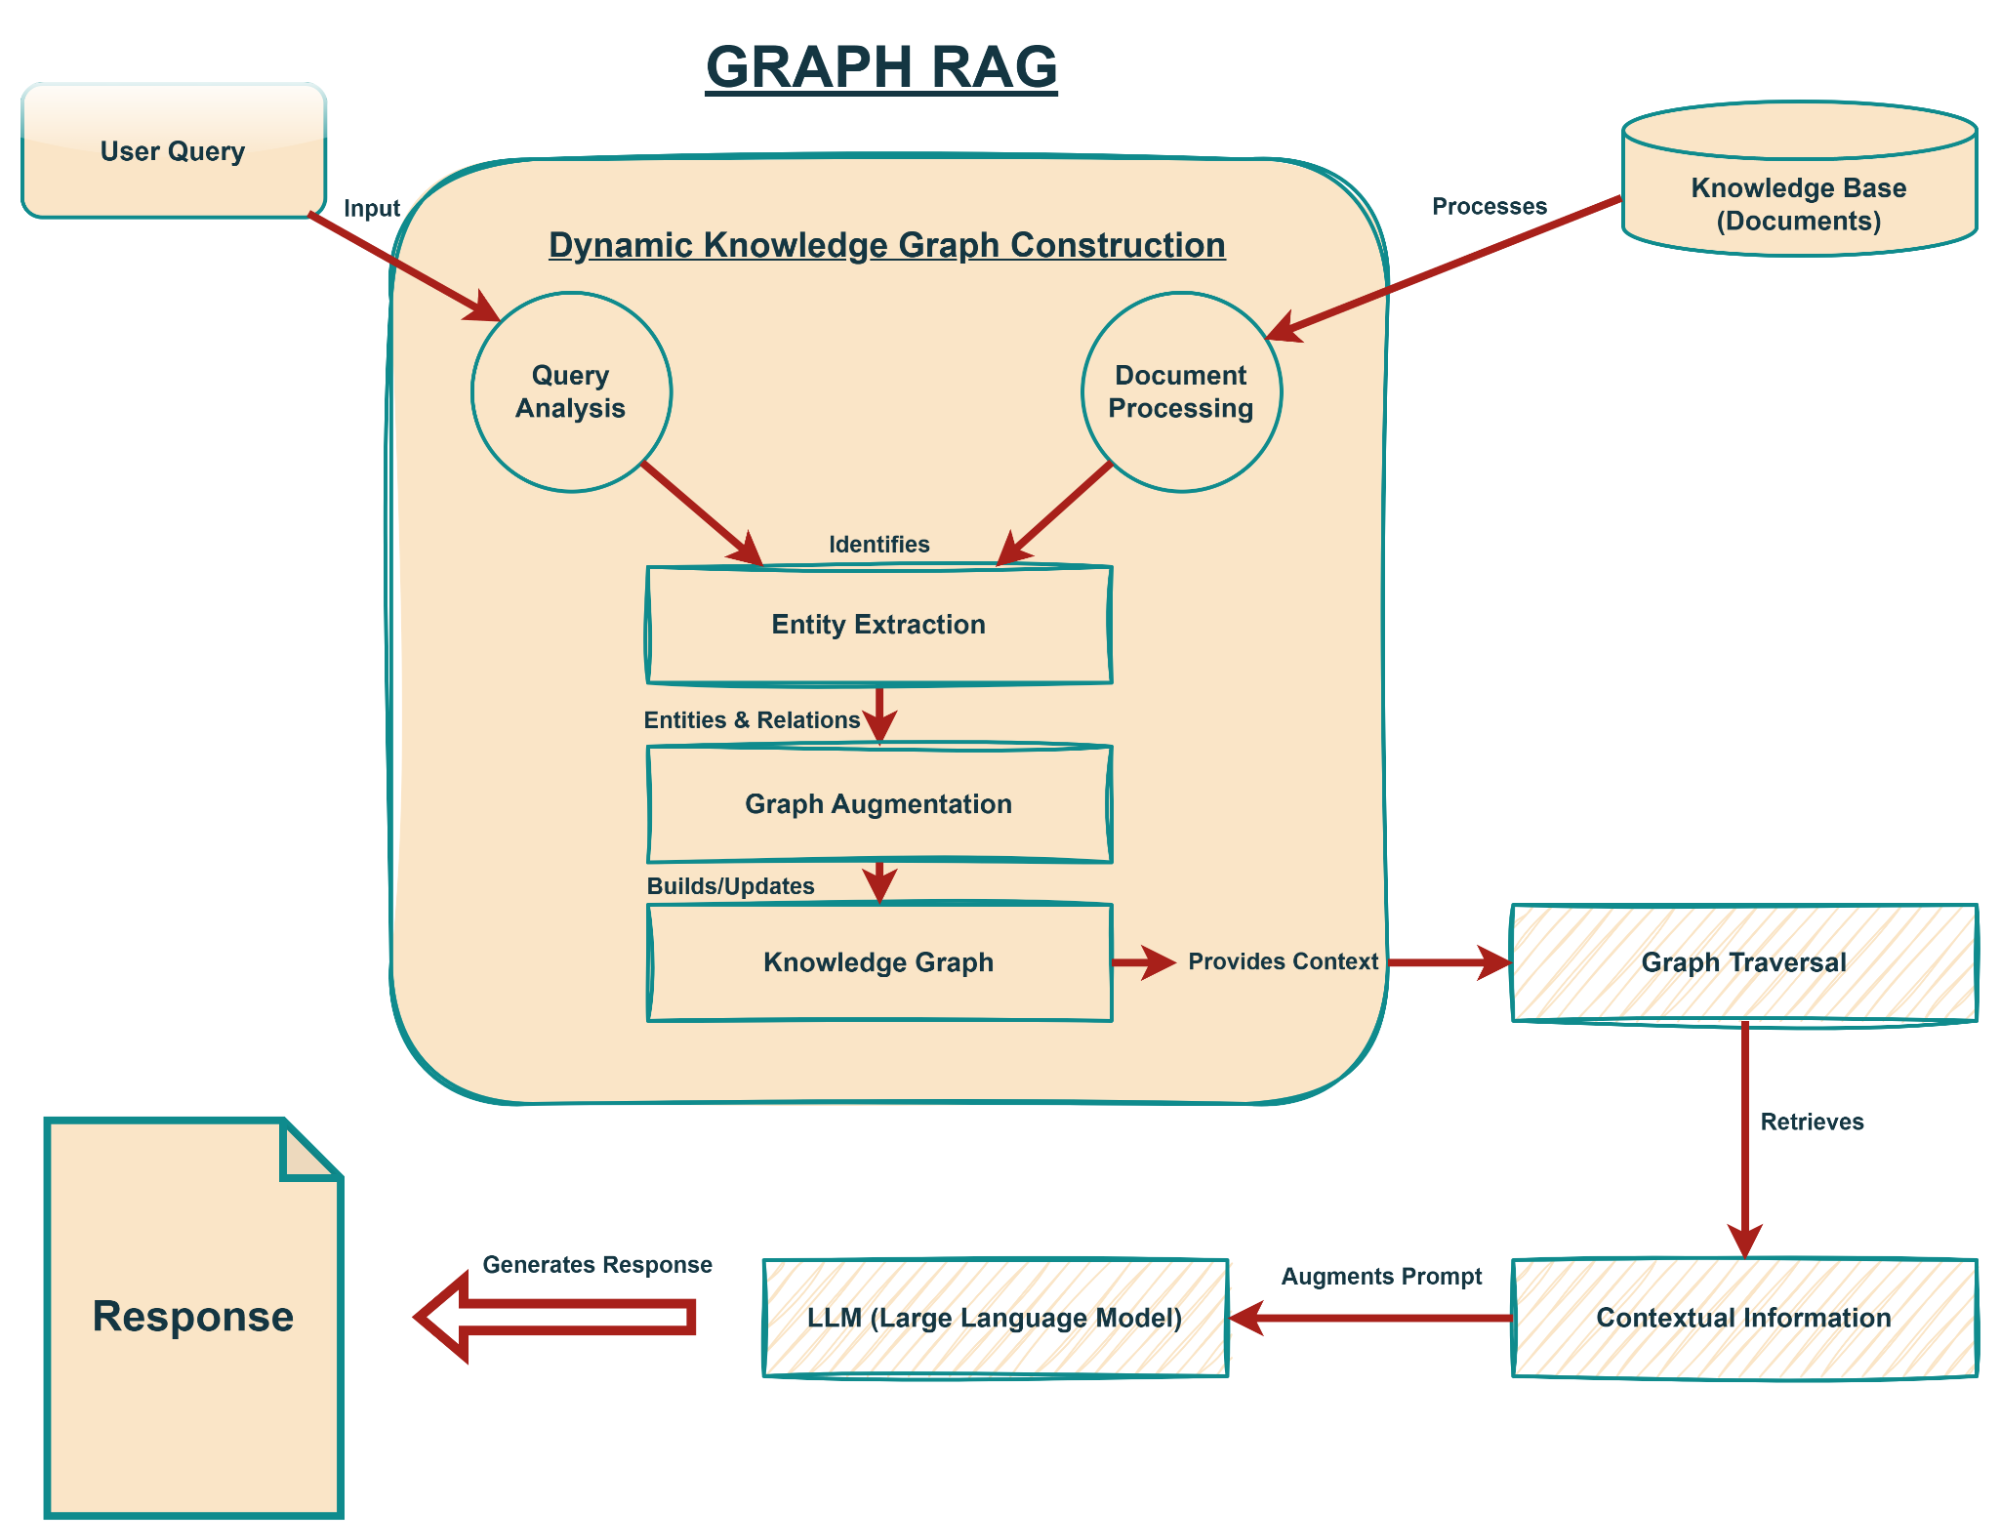
Graph RAG distinguishes itself from conventional RAG architectures by a number of progressive options that collectively contribute to its enhanced retrieval capabilities and contextual understanding. These options will not be merely additive however basically reshape how data is accessed and utilized by LLMs.
Dynamic Information Graph Development
Probably the most important developments of Graph RAG is its potential to assemble a data graph dynamically throughout the retrieval course of.
Conventional data graphs are sometimes pre-built and static, requiring in depth guide effort or advanced ETL (Extract, Remodel, Load) pipelines to take care of and replace. In distinction, Graph RAG builds or expands the graph in actual time primarily based on the entities and relationships recognized from the enter question and preliminary retrieval outcomes.
This on-the-fly development ensures that the data graph is at all times related to the instant context of the consumer’s question, avoiding the overhead of managing an enormous, all-encompassing graph. This dynamic nature permits the system to adapt to new data and evolving contexts with out requiring fixed re-indexing or graph reconstruction.
For example, if a question mentions a newly found scientific idea, Graph RAG can incorporate this into its momentary data graph, linking it to present associated entities, thereby offering up-to-date and related data.
Clever Entity Linking
On the coronary heart of dynamic graph development lies clever entity linking.
As data is processed, Graph RAG identifies key entities (e.g., folks, organizations, areas, ideas) and establishes relationships between them. This goes past easy key phrase matching; it entails understanding the semantic connections between totally different items of knowledge.
For instance, if a doc mentions “GPT-4” and one other mentions “OpenAI,” the system can hyperlink these entities by a “developed by” relationship. This linking course of is essential as a result of it permits the RAG system to traverse the graph and retrieve not simply the direct reply to a question, but in addition associated data that gives richer context.
That is notably helpful in domains the place entities are extremely interconnected, reminiscent of medical analysis, authorized paperwork, or monetary reviews. By linking related entities, Graph RAG ensures a extra complete and interconnected retrieval, enhancing the depth and breadth of the data offered to the LLM.
Contextual Determination-Making with Graph Traversal
Not like vector search, which retrieves data primarily based on semantic similarity in an embedding area, Graph RAG leverages the express relationships throughout the data graph for contextual decision-making.
When a question is posed, the system does not simply pull remoted paperwork; it performs graph traversals, following paths between nodes to determine probably the most related and contextually acceptable data.
This implies the system can reply advanced, multi-hop questions that require connecting disparate items of knowledge.
For instance, to reply “What are the principle analysis areas of the lead scientist at DeepMind?”, a conventional RAG may battle to attach “DeepMind” to its “lead scientist” after which to their “analysis areas” if these items of knowledge are in separate paperwork. Graph RAG, nevertheless, can navigate these relationships instantly throughout the graph, guaranteeing that the retrieved data just isn’t solely correct but in addition deeply contextualized throughout the broader data community.
This functionality considerably improves the system’s potential to deal with nuanced queries and supply extra coherent and logically structured responses.
Confidence Rating Utilization for Refined Retrieval
To additional optimize the retrieval course of and stop the inclusion of irrelevant or low-quality data, Graph RAG makes use of confidence scores derived from the data graph.
These scores will be primarily based on numerous components, such because the energy of relationships between entities, the recency of knowledge, or the perceived reliability of the supply. By assigning confidence scores, the framework can intelligently determine when and the way a lot exterior data to retrieve.
This mechanism acts as a filter, serving to to prioritize high-quality, related data whereas minimizing the addition of noise.
For example, if a specific relationship has a low confidence rating, the system may select to not increase retrieval alongside that path, thereby avoiding the introduction of doubtless deceptive or unverified knowledge.
This selective enlargement ensures that the LLM receives a compact and extremely related set of details, enhancing each effectivity and response accuracy by sustaining a targeted and pertinent data graph for every question.
How Graph RAG Works: A Step-by-Step Breakdown
Understanding the theoretical underpinnings of Graph RAG is crucial, however its true energy lies in its sensible implementation.
This part will stroll by the standard workflow of a Graph RAG system, illustrating every stage with conceptual code examples to offer a clearer image of its operational mechanics.
Whereas the precise implementation might fluctuate relying on the chosen graph database, LLM, and particular use case, the core rules stay constant.
Step 1: Question Evaluation and Preliminary Entity Extraction
The method begins when a consumer submits a question.
Step one for the Graph RAG system is to investigate this question to determine key entities and potential relationships. This typically entails Pure Language Processing (NLP) strategies reminiscent of Named Entity Recognition (NER) and dependency parsing.
Conceptual Code Instance (Python):
import spacy
from sklearn.feature_extraction.textual content import TfidfVectorizer
from sklearn.metrics.pairwise import cosine_similarity
import networkx as nx


nlp = spacy.load("en_core_web_sm")


def extract_entities(question):
    doc = nlp(question)
    return [(ent.text.strip(), ent.label_) for ent in doc.ents]

question = "Who's the CEO of Google and what's their internet price?"
extracted_entities = extract_entities(question)
print(f"🧠 Extracted Entities: {extracted_entities}"
Step 2: Preliminary Retrieval and Candidate Doc Identification
As soon as entities are extracted, the system performs an preliminary retrieval from an enormous corpus of paperwork.
This may be completed utilizing conventional vector search (e.g., cosine similarity on embeddings) or key phrase matching. The purpose right here is to determine a set of candidate paperwork which are probably related to the question.
Conceptual Code Instance (Python – simplified vector search):
corpus = [
    "Sundar Pichai is the CEO of Google.",
    "Google is a multinational technology company.",
    "The net worth of many tech CEOs is in the billions.",
    "Larry Page and Sergey Brin founded Google."
]

vectorizer = TfidfVectorizer()
corpus_embeddings = vectorizer.fit_transform(corpus)

def retrieve_candidate_documents(question, corpus, vectorizer, corpus_embeddings, top_k=2):
    query_embedding = vectorizer.remodel([query])
    similarities = cosine_similarity(query_embedding, corpus_embeddings).flatten()
    top_indices = similarities.argsort()[-top_k:][::-1]
    return [corpus[i] for i in top_indices]


candidate_docs = retrieve_candidate_documents(question, corpus, vectorizer, corpus_embeddings)
print(f"📄 Candidate Paperwork: {candidate_docs}")

Step 3: Dynamic Information Graph Development and Augmentation
That is the core of Graph RAG.
Take a look at our hands-on, sensible information to studying Git, with best-practices, industry-accepted requirements, and included cheat sheet. Cease Googling Git instructions and truly study it!
The extracted entities from the question and the content material of the candidate paperwork are used to dynamically assemble or increase a data graph. This entails figuring out new entities and relationships throughout the textual content and including them as nodes and edges to the graph. If a base data graph already exists, this step augments it; in any other case, it builds a brand new graph from scratch for the present question context.
Conceptual Code Instance (Python – utilizing NetworkX for graph illustration):
def build_or_augment_graph(graph, entities, paperwork):
    for entity, entity_type in entities:
        graph.add_node(entity, kind=entity_type)

    for doc in paperwork:
        doc_nlp = nlp(doc)
        individual = None
        org = None
        for ent in doc_nlp.ents:
            if ent.label_ == "PERSON":
                individual = ent.textual content.strip().strip(".")
            elif ent.label_ == "ORG":
                org = ent.textual content.strip().strip(".")


        if individual and org and "CEO" in doc:
            graph.add_node(individual, kind="PERSON")
            graph.add_node(org, kind="ORG")
            graph.add_edge(individual, org, relation="CEO_of")
    return graph


knowledge_graph = nx.Graph()
knowledge_graph = build_or_augment_graph(knowledge_graph, extracted_entities, candidate_docs)

print("🧩 Graph Nodes:", knowledge_graph.nodes(knowledge=True))
print("🔗 Graph Edges:", knowledge_graph.edges(knowledge=True))

Step 4: Graph Traversal and Contextual Data Retrieval
With the dynamic data graph in place, the system performs graph traversals ranging from the question entities. It explores the relationships (edges) and related entities (nodes) to retrieve contextually related data.
This step is the place the “graph” in Graph RAG actually shines, permitting for multi-hop reasoning and the invention of implicit connections.
Conceptual Code Instance (Python – graph traversal):
def traverse_graph_for_context(graph, start_entity, depth=2):
    contextual_info = set()
    visited = set()
    queue = [(start_entity, 0)]

    whereas queue:
        current_node, current_depth = queue.pop(0)
        if current_node in visited or current_depth > depth:
            proceed
        visited.add(current_node)
        contextual_info.add(current_node)

        for neighbor in graph.neighbors(current_node):
            edge_data = graph.get_edge_data(current_node, neighbor)
            if edge_data:
                relation = edge_data.get("relation", "unknown")
                contextual_info.add(f"{current_node} {relation} {neighbor}")
            queue.append((neighbor, current_depth + 1))
    return checklist(contextual_info)

context = traverse_graph_for_context(knowledge_graph, "Google")
print(f"🔍 Contextual Data from Graph: {context}")

Step 5: Confidence Rating-Guided Enlargement (Non-obligatory however Advisable)
As talked about within the options, confidence scores can be utilized to information the graph traversal.
This ensures that the enlargement of retrieved data is managed and avoids pulling in irrelevant or low-quality knowledge. This may be built-in into Step 4 by assigning scores to edges or nodes and prioritizing high-scoring paths.
Step 6: Data Synthesis and LLM Augmentation
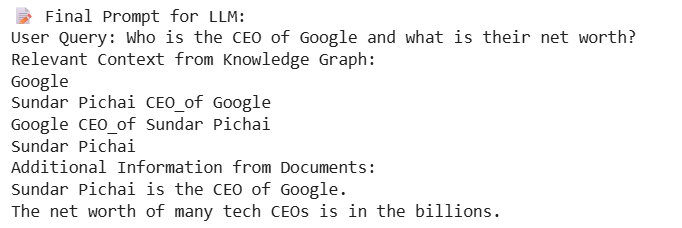
The retrieved contextual data from the graph, together with the unique question and probably the preliminary candidate paperwork, is then synthesized right into a coherent immediate for the LLM.
This enriched immediate gives the LLM with a a lot deeper and extra structured understanding of the consumer’s request.
Conceptual Code Instance (Python):
def synthesize_prompt(question, contextual_info, candidate_docs):
    return "n".be part of([
        f"User Query: {query}",
        "Relevant Context from Knowledge Graph:",
        "n".join(contextual_info),
        "Additional Information from Documents:",
        "n".join(candidate_docs)
    ])


final_prompt = synthesize_prompt(question, context, candidate_docs)
print(f"n📝 Ultimate Immediate for LLM:n{final_prompt}")
Step 7: LLM Response Era
Lastly, the LLM processes the augmented immediate and generates a response.
As a result of the immediate is wealthy with contextual and interconnected data, the LLM is healthier outfitted to offer correct, complete, and coherent solutions.
Conceptual Code Instance (Python – utilizing a placeholder LLM name):
def generate_llm_response(immediate):
    if "Sundar" in immediate and "CEO of Google" in immediate:
        return "Sundar Pichai is the CEO of Google. He oversees the corporate and has a major internet price."
    return "I want extra data to reply that precisely."

llm_response = generate_llm_response(final_prompt)
print(f"n💬 LLM Response: {llm_response}
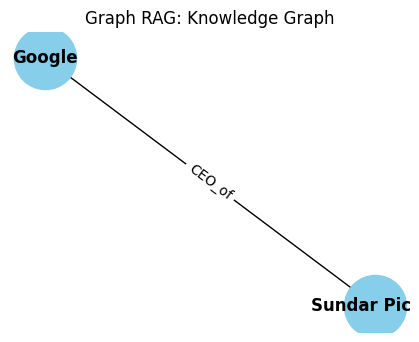
import matplotlib.pyplot as plt

plt.determine(figsize=(4, 3))
pos = nx.spring_layout(knowledge_graph)
nx.draw(knowledge_graph, pos, with_labels=True, node_color='skyblue', node_size=2000, font_size=12, font_weight='daring')
edge_labels = nx.get_edge_attributes(knowledge_graph, 'relation')
nx.draw_networkx_edge_labels(knowledge_graph, pos, edge_labels=edge_labels)
plt.title("Graph RAG: Information Graph")
plt.present()

This step-by-step course of, notably the dynamic graph development and traversal, permits Graph RAG to maneuver past easy key phrase or semantic similarity, enabling a extra profound understanding of knowledge and resulting in superior response technology.
The mixing of graph buildings gives a robust mechanism for contextualizing data, which is a vital consider reaching high-quality RAG outputs.
Sensible Functions and Use Instances of Graph RAG
Graph RAG isn’t just a theoretical idea; its potential to know and leverage relationships inside knowledge opens up a myriad of sensible functions throughout numerous industries. By offering LLMs with a richer, extra interconnected context, Graph RAG can considerably improve efficiency in eventualities the place conventional RAG may fall quick. Listed below are some compelling use instances:
1. Enhanced Enterprise Information Administration
Giant organizations typically battle with huge, disparate data bases, together with inner paperwork, reviews, wikis, and buyer assist logs. Conventional search and RAG methods can retrieve particular person paperwork, however they typically fail to attach associated data throughout totally different silos.
Graph RAG can construct a dynamic data graph from these numerous sources, linking workers to tasks, tasks to paperwork, paperwork to ideas, and ideas to exterior laws or {industry} requirements. This enables for:
-
Clever Q&A for Staff: Staff can ask advanced questions like “What are the compliance necessities for Undertaking X, and which group members are consultants in these areas?” Graph RAG can traverse the graph to determine related compliance paperwork, hyperlink them to particular laws, after which discover the staff related to these laws or Undertaking X.
-
Automated Report Era: By understanding the relationships between knowledge factors, Graph RAG can collect all essential data for complete reviews, reminiscent of undertaking summaries, danger assessments, or market analyses, considerably lowering guide effort.
-
Onboarding and Coaching: New hires can shortly stand up to hurry by querying the data base and receiving contextually wealthy solutions that specify not simply what one thing is, but in addition the way it pertains to different inner processes, instruments, or groups.
2. Superior Authorized and Regulatory Compliance
The authorized and regulatory domains are inherently advanced, characterised by huge quantities of interconnected paperwork, precedents, and laws. Understanding the relationships between totally different authorized clauses, case legal guidelines, and regulatory frameworks is vital. Graph RAG is usually a game-changer right here:
-
Contract Evaluation: Legal professionals can use Graph RAG to investigate contracts, determine key clauses, obligations, and dangers, and hyperlink them to related authorized precedents or regulatory acts. A question like “Present me all clauses on this contract associated to knowledge privateness and their implications beneath GDPR” will be answered comprehensively by traversing the graph of authorized ideas.
-
Regulatory Impression Evaluation: When new laws are launched, Graph RAG can shortly determine all affected inner insurance policies, enterprise processes, and even particular tasks, offering a holistic view of the compliance impression.
-
Litigation Assist: By mapping relationships between entities in case paperwork (e.g., events, dates, occasions, claims, proof), Graph RAG will help authorized groups shortly determine connections, uncover hidden patterns, and construct stronger arguments.
3. Scientific Analysis and Drug Discovery
Scientific literature is rising exponentially, making it difficult for researchers to maintain up with new discoveries and their interconnections. Graph RAG can speed up analysis by creating dynamic data graphs from scientific papers, patents, and scientific trial knowledge:
-
Speculation Era: Researchers can question the system about potential drug targets, illness pathways, or gene interactions. Graph RAG can join details about compounds, proteins, ailments, and analysis findings to counsel novel hypotheses or determine gaps in present data.
-
Literature Evaluate: As a substitute of sifting by 1000’s of papers, researchers can ask questions like “What are the identified interactions between Protein A and Illness B, and which analysis teams are actively engaged on this?” The system can then present a structured abstract of related findings and researchers.
-
Medical Trial Evaluation: Graph RAG can hyperlink affected person knowledge, therapy protocols, and outcomes to determine correlations and insights which may not be obvious by conventional statistical evaluation, aiding in drug growth and customized medication.
4. Clever Buyer Assist and Chatbots
Whereas many chatbots exist, their effectiveness is usually restricted by their lack of ability to deal with advanced, multi-turn conversations that require deep contextual understanding. Graph RAG can energy next-generation buyer assist methods:
-
Complicated Question Decision: Prospects typically ask questions that require combining data from a number of sources (e.g., product manuals, FAQs, previous assist tickets, consumer boards). A question like “My good residence machine is not connecting to Wi-Fi after the most recent firmware replace; what are the troubleshooting steps and identified compatibility points with my router mannequin?” will be resolved by a Graph RAG-powered chatbot that understands the relationships between gadgets, firmware variations, router fashions, and troubleshooting procedures.
-
Personalised Suggestions: By understanding a buyer’s previous interactions, preferences, and product utilization (represented in a graph), the system can present extremely customized product suggestions or proactive assist.
-
Agent Help: Customer support brokers can obtain real-time, contextually related data and options from a Graph RAG system, considerably enhancing decision occasions and buyer satisfaction.
These use instances spotlight Graph RAG’s potential to rework how we work together with data, shifting past easy retrieval to true contextual understanding and clever reasoning. By specializing in the relationships inside knowledge, Graph RAG unlocks new ranges of accuracy, effectivity, and perception in AI-powered functions.
Conclusion
Graph RAG represents a major evolution within the area of Retrieval-Augmented Era, shifting past the restrictions of conventional vector-based retrieval to harness the facility of interconnected data. By dynamically developing and leveraging data graphs, Graph RAG permits Giant Language Fashions to entry and synthesize data with unprecedented contextual depth and accuracy.
This strategy not solely enhances the factual grounding of LLM responses but in addition unlocks the potential for extra subtle reasoning, multi-hop query answering, and a deeper understanding of advanced relationships inside knowledge.
The sensible functions of Graph RAG are huge and transformative, spanning enterprise data administration, authorized and regulatory compliance, scientific analysis, and clever buyer assist. In every of those domains, the flexibility to navigate and perceive the intricate internet of knowledge by a graph construction results in extra exact, complete, and dependable AI-powered options. As knowledge continues to develop in complexity and interconnectedness, Graph RAG provides a sturdy framework for constructing clever methods that may actually comprehend and make the most of the wealthy tapestry of human data.
Whereas the implementation of Graph RAG might contain overcoming challenges associated to graph development, entity extraction, and environment friendly traversal, the advantages when it comes to enhanced LLM efficiency and the flexibility to sort out real-world issues with higher efficacy are simple.
As analysis and growth on this space proceed, Graph RAG is poised to grow to be an indispensable part within the structure of superior AI methods, paving the way in which for a future the place AI can purpose and reply with a stage of intelligence that actually mirrors human understanding.
Continuously Requested Questions
1. What’s the main benefit of Graph RAG over conventional RAG?
The first benefit of Graph RAG is its potential to know and leverage the relationships between entities and ideas inside a data graph. Not like conventional RAG, which frequently depends on semantic similarity in vector area, Graph RAG can carry out multi-hop reasoning and retrieve contextually wealthy data by traversing express connections, resulting in extra correct and complete responses.
2. How does Graph RAG deal with new data or evolving data?
Graph RAG employs dynamic data graph development. This implies it will probably construct or increase the data graph in real-time primarily based on the entities recognized within the consumer question and retrieved paperwork. This on-the-fly functionality permits the system to adapt to new data and evolving contexts with out requiring fixed re-indexing or guide graph updates.
3. Is Graph RAG appropriate for every type of knowledge?
Graph RAG is especially efficient for knowledge the place relationships between entities are essential for understanding and answering queries. This consists of structured, semi-structured, and unstructured textual content that may be reworked right into a graph illustration. Whereas it will probably work with numerous knowledge sorts, its advantages are most pronounced in domains wealthy with interconnected data, reminiscent of authorized paperwork, scientific literature, or enterprise data bases.
4. What are the principle parts required to construct a Graph RAG system?
Key parts usually embody:
- **LLM (Giant Language Mannequin): **For producing responses.
Graph Database (or Graph Illustration Library): To retailer and handle the data graph (e.g., Neo4j, Amazon Neptune, NetworkX). - Data Extraction Module: For Named Entity Recognition (NER) and Relation Extraction (RE) to populate the graph.
Retrieval Module: To carry out preliminary doc retrieval after which graph traversal. - Immediate Engineering Module: To synthesize the retrieved graph context right into a coherent immediate for the LLM.
5. What are the potential challenges in implementing Graph RAG?
Challenges can embody:
- Complexity of Graph Development: Precisely extracting entities and relations from unstructured textual content will be difficult.
- Scalability: Managing and traversing very giant data graphs effectively will be computationally intensive.
- Knowledge High quality: The standard of the generated graph closely depends upon the standard of the enter knowledge and the extraction fashions.
- Integration: Seamlessly integrating numerous parts (LLM, graph database, NLP instruments) can require important engineering effort.
6. Can Graph RAG be mixed with different RAG strategies?
Sure, Graph RAG will be mixed with different RAG strategies. For example, preliminary retrieval can nonetheless leverage vector search to slender down the related doc set, after which Graph RAG will be utilized to those candidate paperwork to construct a extra exact contextual graph. This hybrid strategy can provide one of the best of each worlds: the broad protection of vector search and the deep contextual understanding of graph-based retrieval.
7. How does confidence scoring work in Graph RAG?
Confidence scoring in Graph RAG entails assigning scores to nodes and edges throughout the dynamically constructed data graph. These scores can replicate the energy of a relationship, the recency of knowledge, or the reliability of its supply. The system makes use of these scores to prioritize paths throughout graph traversal, guaranteeing that solely probably the most related and high-quality data is retrieved and used to reinforce the LLM immediate, thereby minimizing irrelevant additions.
References
- Graph RAG: Dynamic Information Graph Development for Enhanced Retrieval
Word: This can be a conceptual article primarily based on the rules of Graph RAG. Particular analysis papers on “Graph RAG” as a unified idea are rising, however the underlying concepts draw from data graphs, RAG, and dynamic graph development.
Authentic Jupyter Pocket book (for code examples and base content material)
- Retrieval-Augmented Era (RAG)
Lewis, P., et al. (2020). Retrieval-Augmented Era for Information-Intensive NLP Duties. arXiv preprint arXiv:2005.11401. https://arxiv.org/abs/2005.11401 - Information Graphs
Ehrlinger, L., & Wöß, W. (2016). Information Graphs: An Introduction to Their Creation and Utilization. In Semantic Internet Challenges (pp. 1-17). Springer, Cham. https://hyperlink.springer.com/chapter/10.1007/978-3-319-38930-1_1 - Named Entity Recognition (NER) and Relation Extraction (RE)
Nadeau, D., & Sekine, S. (2007). A survey of named entity recognition and classification. Lingvisticae Investigationes, 30(1), 3-26.
https://www.researchgate.internet/publication/220050800_A_survey_of_named_entity_recognition_and_classification - NetworkX (Python Library for Graph Manipulation)
https://networkx.org/ - spaCy (Python Library for NLP)
https://spacy.io/ - scikit-learn (Python Library for Machine Studying)
https://scikit-learn.org/

